Industry
When to Use Multiple Aggregators in Fintech
The fintech landscape is rapidly evolving and to stay competitive, companies must deliver innovative solutions that offer seamless user experiences and comprehensive functionality. Data aggregators play a crucial role in this process, enabling fintech applications to access and utilize vast amounts of financial data from a variety of sources. However, there comes a point when relying on a single aggregator may limit your fintech solution's scalability and flexibility.
What are Data Aggregators?
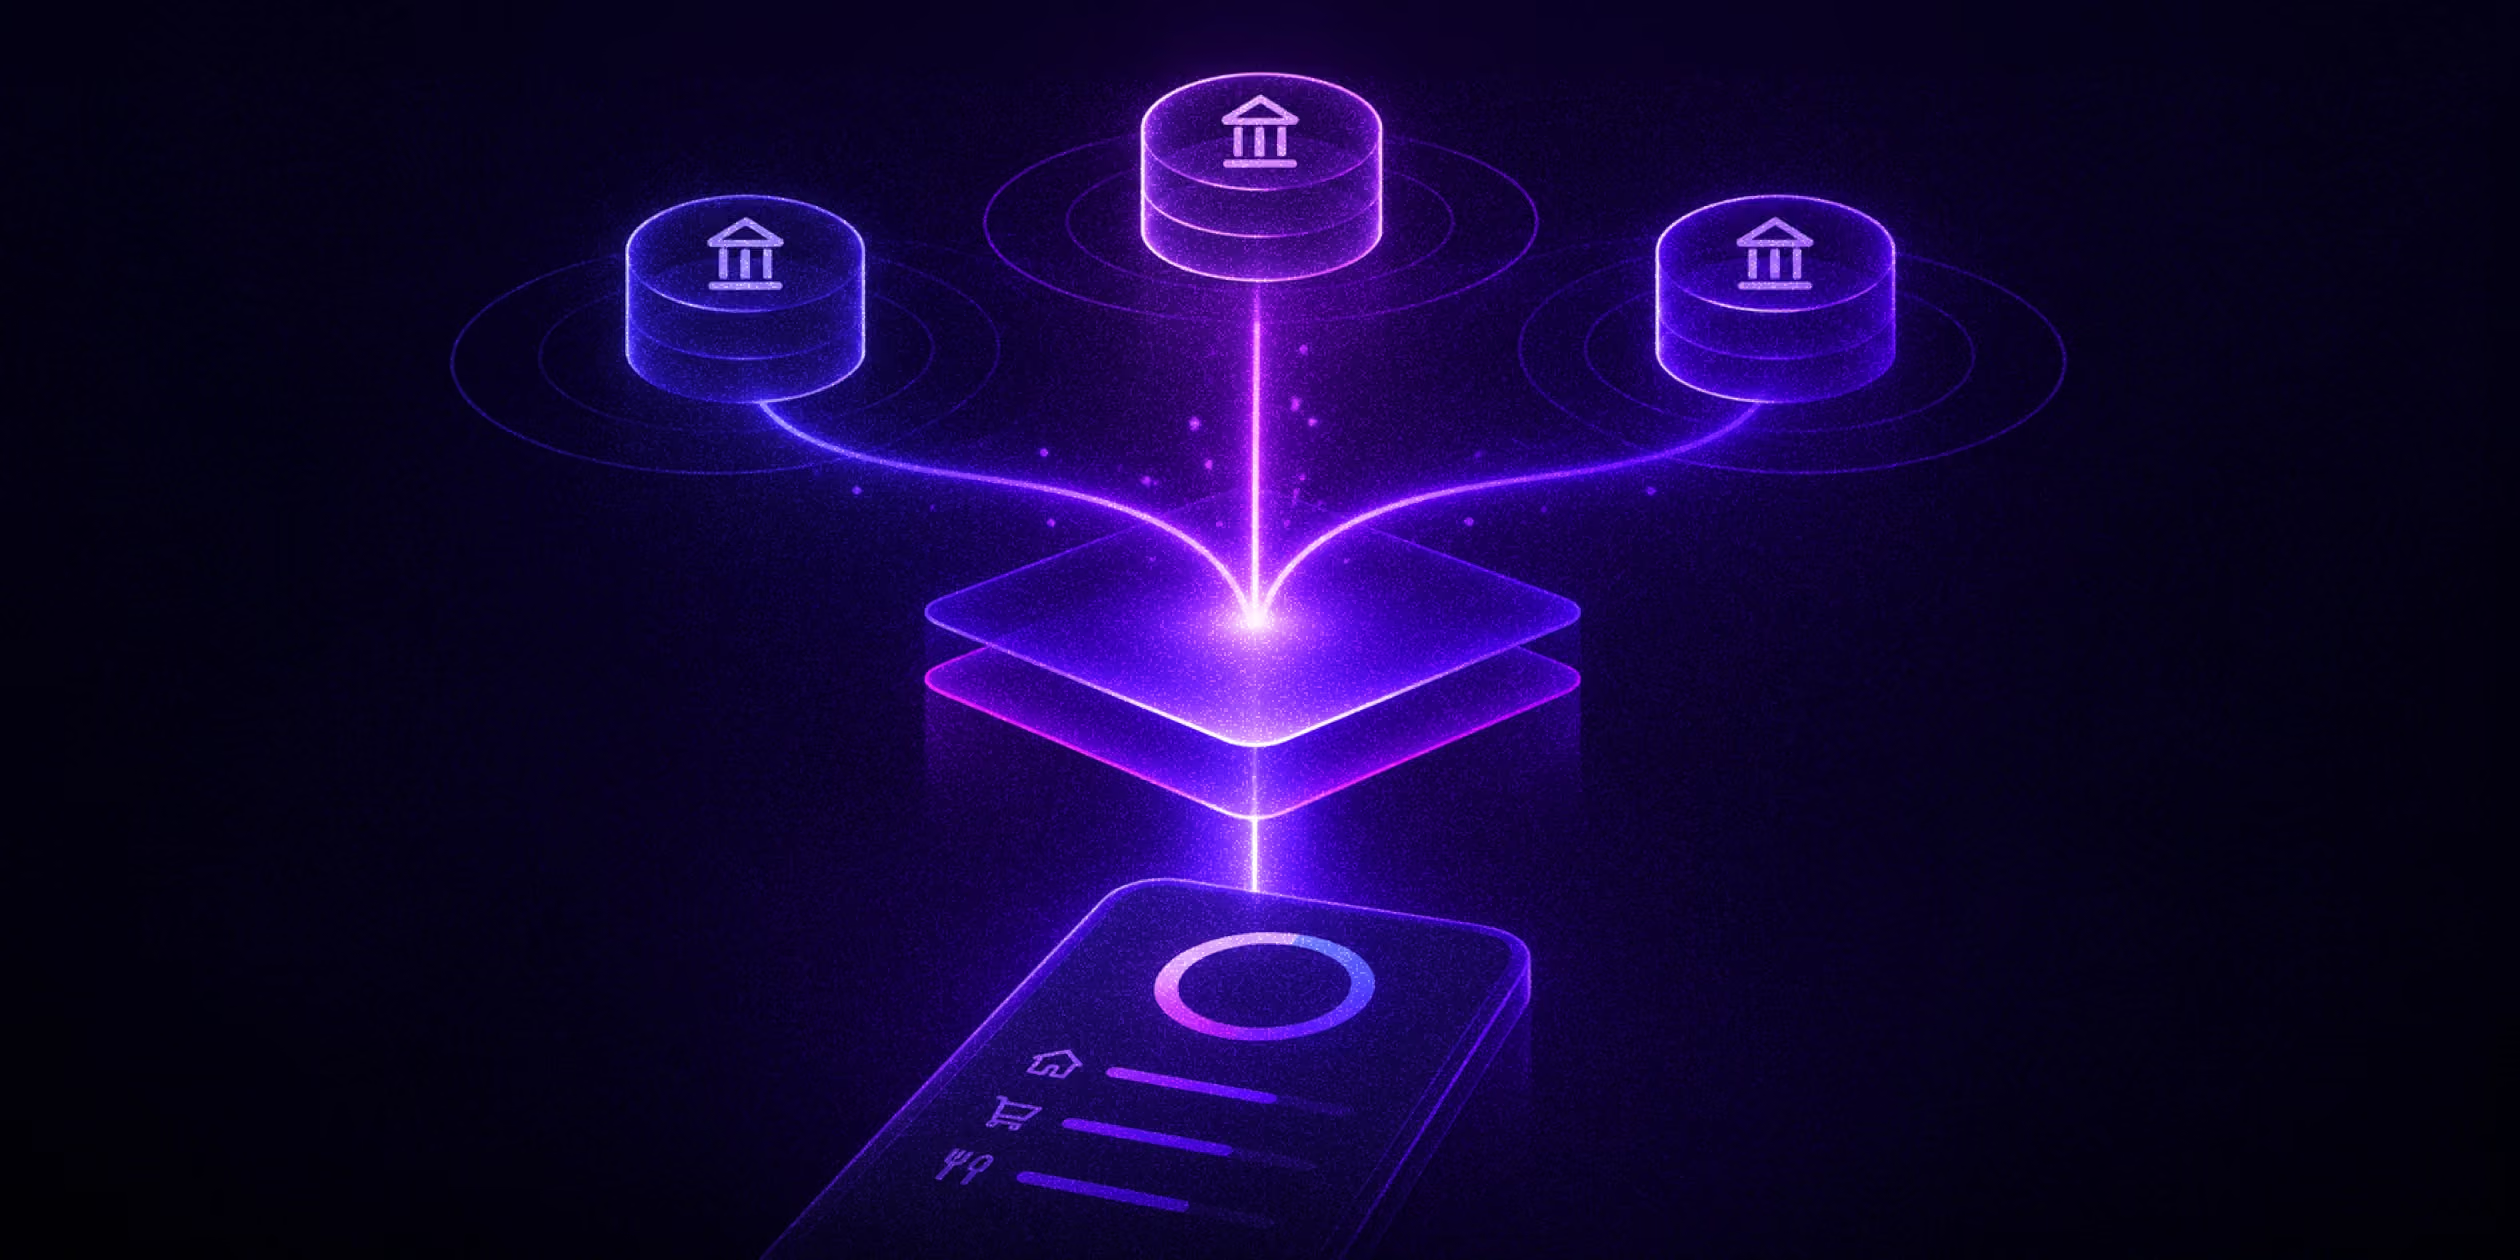
Data aggregators act as intermediaries between user financial accounts and financial applications. They securely connect a fintech app to various financial institutions like banks, credit card providers, and investment platforms. Aggregators use APIs to gather user data (with the user's explicit consent) such as account balances, transaction histories, and investment holdings. This consolidated data is essential for applications offering personal finance management, budgeting tools, lending platforms, and other innovative fintech solutions.
The Advantages of Using Multiple Aggregators
- Expanded Coverage: No single data aggregator covers every single financial institution. Employing multiple aggregators dramatically widens the net of institutions your fintech solution can connect to, increasing your potential customer base.
- Enhanced Reliability: Aggregators can sometimes experience outages or service disruptions. If your fintech solution relies solely on one aggregator, any downtime translates to downtime for your users. With multiple aggregators in place, you have built-in redundancy; if one fails, others can pick up the slack, minimizing interruptions.
- Optimized Data Quality: Different aggregators may have varying strengths in the types of data they collect or the accuracy level of specific data points. Using multiple aggregators allows you to cross-reference and potentially improve the overall quality of the financial data available to your solution.
- Competitive Pricing: Introducing competition among aggregators can help you negotiate more favorable pricing and terms for their services.
When to Consider Multiple Aggregators
Here are key scenarios where using multiple aggregators becomes particularly beneficial:
- Targeting Diverse Geographic Markets: If you plan to expand your fintech solution into new countries or regions, you'll likely encounter different established aggregators in each area. Instead of trying to shoehorn one aggregator into global compatibility, it's wiser to incorporate multiple ones to ensure optimal coverage.
- Offering Niche Products: Serving a niche market with specific financial needs may require data only available from specialized aggregators. Using multiple aggregators grants you access to this granular data.
- Scaling Rapidly: As your fintech solution gains traction and your user base expands, the volume and diversity of data requests will increase. Having multiple aggregators distributes the load, preventing bottlenecks and maintaining responsiveness for your users.
- Demanding High Reliability: If your fintech application is mission-critical (for example, real-time trading or lending platforms), relying on a single aggregator poses a significant risk. Multiple aggregators establish essential fault tolerance.
Challenges and Best Practices
Picture this: you've decided it's time for your fintech to branch out, to go after those untapped markets and really conquer some ground. But as you build those connections, you realize each aggregator is like its own little world. They speak a different language of APIs, have data organized their own way, and handle things a bit differently from the ones you're used to. It's like trying to put together a big, beautiful puzzle where the pieces don't quite match up.
Of course, this isn't the only challenge. What if two aggregators have slightly conflicting information for the same account? Now you have to play financial detective and figure out which source is the most reliable. And then there's the cost – each aggregator is one more for the budget.
Best Practices for Multi-Aggregator Success
Let's make things smoother. First, think of a translator. In your software, build a layer that takes all that messy, mismatched aggregator data and makes it speak the same language to your fintech solution. This translator is your new best friend, saving time and sanity.
Next, safety nets! Imagine your primary aggregator has a hiccup. Suddenly, users see errors instead of their balances. Not good. Your system needs to be clever enough to switch to a backup aggregator automatically, as if the problem never happened. Your users might never need to know!
Finally, there's the matter of playing detective when data clashes. It's time to create some rules. Maybe you always trust the newest data, or maybe you have a system to favor aggregators known for accuracy in certain areas. This way, your fintech app always puts its best foot forward.
Let's Wrap It Up
Let's be real, multiple aggregators aren't always a walk in the park. There's extra work, extra cost, but the potential for reaching new markets, providing rock-solid reliability, and having top-notch data makes it worth the effort. With a bit of smart planning and a focus on the user experience, you'll navigate this multiple aggregator world like a pro.
Frequently Asked Questions
What is the difference between an aggregator and a super aggregator?
An aggregator connects your application to financial institutions and returns account and transaction data. A super aggregator sits above several aggregators and exposes them through one API, the model Quiltt runs. You get broader coverage and fallback routing without integrating each provider yourself.
Why doesn't a provider like Plaid have business bank coverage that matches consumer bank coverage?
Plaid, like most aggregators, prioritizes its coverage around expected volume. The institutions that power consumer fintech (e.g. Chase, Bank of America, Wells Fargo) get prioritized because they drive the most connections and therefore the most revenue. Business-focused banks like Brex, Ramp, and Mercury, along with thousands of smaller commercial banks, usually fall outside the top 100 most-integrated institutions at any major aggregator. The underlying commercial model wasn't designed for the long-tail, high-value connectivity that B2B fintech requires.
Why does adding a second bank aggregator require rebuilding existing code rather than extending it?
An application built around a single aggregator encodes that provider's data model throughout the codebase: in the schema, the connection flow, and the error handling. Adding a second provider introduces a second data model that has to be reconciled at every point the first one was assumed. A normalization layer has to sit above both so the rest of the application sees one consistent shape. Without it, every downstream component (the frontend, the models, the webhooks) has to be updated to handle provider-specific variations. What looked like a deferred decision becomes technical debt distributed across the codebase, surfacing at exactly the moment the team is under pressure to fix a coverage gap.